A direct API call is enough for a prototype. Production image processing needs a little more structure because uploads are large, providers can rate-limit requests, and users expect a failed job to be recoverable. These practices keep the workflow predictable as volume grows.
Use an asynchronous job boundary
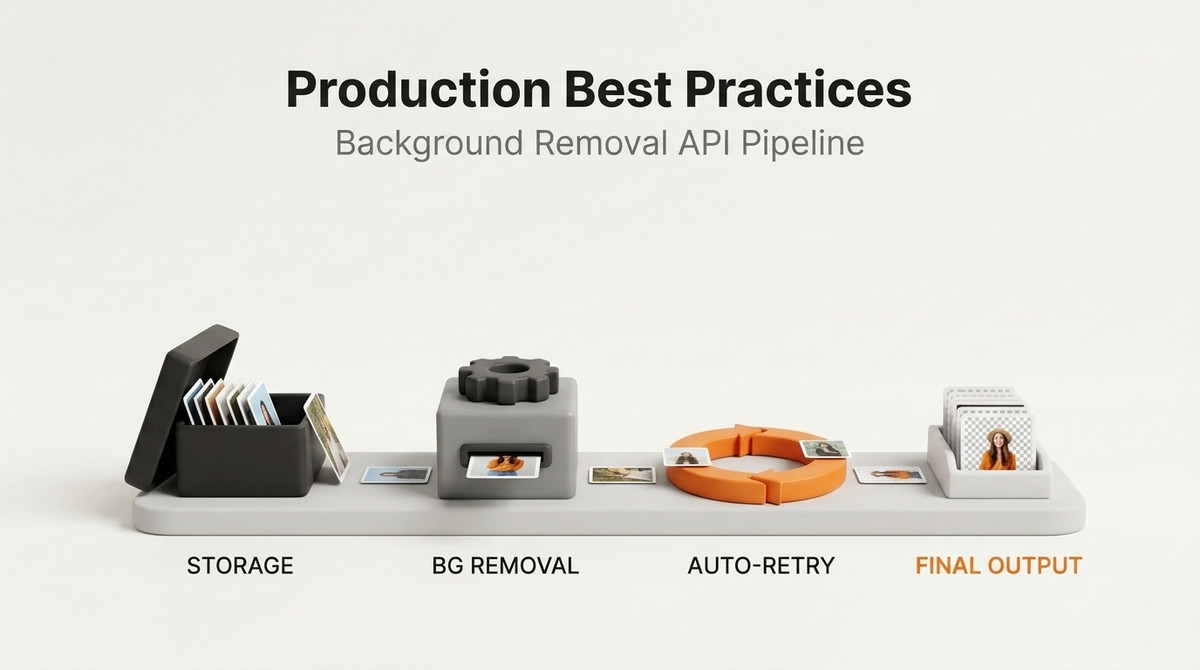
Accept the upload, persist the original in object storage, and create a job record with a pending status. A worker can then call the API and update the record to completed or failed. The user interface can poll the job or receive a webhook rather than waiting for an image request to finish.
- Validate and store the original upload.
- Create a job with a stable ID and enqueue it.
- Call
https://fapihub.com/v2/rembg/from a server-side worker. - Store the PNG and publish the completed status.
Retry only recoverable failures
Retry timeouts, connection errors, 5xx responses, and 429 Too Many Requests with exponential backoff, and honor the Retry-After header when it is present. Do not blindly retry invalid files, authentication errors, or other 4xx responses. A short retry policy might use delays of 1, 2, and 4 seconds before marking the job for review.
import time

RETRYABLE_STATUS_CODES = {429, 500, 502, 503, 504}

def should_retry(response):
    return response is None or response.status_code in RETRYABLE_STATUS_CODES

for attempt in range(4):
    response = send_request()  # returns None on timeout or connection error
    if response is not None and response.status_code == 200:
        save_result(response.content)
        break
    if not should_retry(response) or attempt == 3:
        mark_failed(response.status_code if response is not None else "network")
        break
    retry_after = response.headers.get("Retry-After") if response is not None else None
    time.sleep(int(retry_after) if retry_after else 2 ** attempt)
Make jobs idempotent
Use a digest of the original bytes, processing options, and model as an idempotency key. If a worker crashes after the API succeeds but before your database is updated, a repeat job can reuse the existing result rather than creating duplicate work.
Validate the result
Check the response status, content type, and file signature before publishing the output. Store the original dimensions and the output dimensions for debugging. Keep the input available for a limited retention period so support teams can investigate edge cases without retaining user data indefinitely.
Validate inputs before they cost a request
Successful requests and 4xx client errors both count against your quota; only 5xx server errors are free. That makes cheap local checks worth doing before a job reaches the worker. The API accepts JPEG, PNG, WebP, BMP, and GIF files up to 10 MB, so reject anything else at upload time.
- Check the size limit before reading the whole body into memory.
- Detect the format from the file signature, not from the extension or the client's MIME type.
- Decode the image once with a library such as Pillow or Sharp to catch truncated uploads.
- Downscale oversized originals that exceed 10 MB instead of failing the job, and record that you did.
from io import BytesIO
from PIL import Image

MAX_BYTES = 10 * 1024 * 1024
ALLOWED_FORMATS = {"JPEG", "PNG", "WEBP", "BMP", "GIF"}

def validate_upload(data: bytes) -> str | None:
    """Return an error message, or None if the file can be sent."""
    if len(data) > MAX_BYTES:
        return "File is larger than 10 MB"
    try:
        with Image.open(BytesIO(data)) as img:
            if img.format not in ALLOWED_FORMATS:
                return f"Unsupported format: {img.format}"
            img.verify()  # catches truncated or corrupt files
    except Exception:
        return "File is not a readable image"
    return None
Map every error code to an action
The retry policy above decides whether to try again. A production worker also needs to decide what happens to the job and who gets notified. Errors arrive as JSON with code, message, and request_id fields; store all three on the job record.
| Status and code | Job outcome | Operational response |
|---|---|---|
400 invalid_image | Fail permanently | Tell the uploader the file could not be processed. Track the rate; a spike usually points to an upload bug. |
401 invalid_api_key | Hold, do not fail | Stop all workers and page the owner. Every job will fail until the key is fixed. |
402 insufficient_credits | Hold, do not fail | Pause the queue and alert billing owners. Resume after an upgrade or the next billing period. |
429 rate_limit_exceeded | Requeue | Wait for Retry-After seconds. Persistent 429s mean concurrency is set too high. |
| 5xx | Retry, then review | Retry with backoff (free against quota). If failures continue, pause new work and keep jobs pending. |
The distinction between fail and hold matters. A job that failed because your key was rotated is not the user's fault, and it should resume automatically once the configuration is fixed rather than sitting in a failed state that someone has to reprocess by hand.
Size concurrency to the rate limit
Each FAPIhub plan has a per-minute rate limit, and the right worker count depends on your plan and on how long each request takes. Rather than hard-coding a large number, start with a small pool and let the system tell you when it is too aggressive:
- Run a fixed pool of workers that each process one job at a time.
- Share a single limiter across workers so total throughput is controlled, not per-worker throughput.
- On a 429, pause the shared limiter for the
Retry-Afterduration instead of letting each worker back off independently. - Log the 429 rate. If it stays above zero in normal operation, reduce the pool size.
A shared pause matters because independent backoff in many workers tends to synchronize: they all wake up at the same moment and hit the limit again. Adding a small random jitter to each delay spreads them out.
Plan capacity and cost
Pick a plan from your expected monthly volume plus headroom for 4xx errors and re-processing, since those count as requests. Using the current plan prices:
| Monthly volume | Plan that covers it | Price |
|---|---|---|
| Up to 100 | Basic (free) | $0 |
| Up to 7,500 | Pro | $15/month |
| Up to 52,000 | Ultra | $79/month |
| Up to 255,000 | Mega | $199/month |
| Irregular or one-off | Per Usage | $10 per 1,000 requests, never expire |
As a worked example, a marketplace processing 30,000 new listing photos a month, with roughly 5% of uploads rejected or re-run, needs about 31,500 requests. Pro's 7,500 is not enough; Ultra at $79 covers it with room for growth. A one-time backfill of 4,000 archived images, by contrast, fits four per-usage packs for $40 and does not require changing the monthly plan. See pricing for current details and our cost comparison for how this compares with other providers.
Set an alert well before the monthly allowance runs out. A 402 in production is avoidable if someone sees usage trending up a week earlier; your dashboard shows current usage for the billing period.
Pre-launch checklist
- Uploads are validated for format, size, and decodability before enqueueing.
- Jobs have explicit states, including a
heldstate for key and quota problems. - Retries cover only 429, 5xx, and network errors, with jitter and
Retry-Aftersupport. - Concurrency is controlled by one shared limiter.
- Error
codeandrequest_idare stored on each failed job. - Results are verified as PNG and cached by idempotency key.
- Usage alerts fire before the plan quota is reached.
- The API key lives only in backend secret storage.
Measure the workflow
Track queue wait time, API duration, successful jobs, retry count, and failure reason. Alert on changes in failure rate and latency rather than only on worker crashes. These metrics tell you whether a problem is in your upload path, queue, provider request, or storage layer.
Protect the API key
Only call the API from trusted backend code. Keep the key in environment or secret management, redact it from logs, and rotate it when team access changes. Never place it in browser JavaScript or a mobile app bundle.
These patterns apply whether you process a few hundred catalog images or a continuous stream of user uploads. Start with a queue, explicit states, and useful logs; add concurrency only after the basic workflow is observable.
Frequently asked questions
Should a worker retry a 402 insufficient_credits error?
Not on a timer. The quota will not reset until you upgrade or the next billing period starts, so retries only add noise. Hold the affected jobs, pause the queue, and resume once the plan has capacity.
Do retries cost extra requests?
Retries after 5xx errors do not, because 5xx responses are never counted against your quota. A retry that eventually succeeds counts once, as a successful request. Retrying a 400 does count each time, which is why invalid files should fail immediately.
How many workers should I run?
It depends on your plan's per-minute rate limit and your request latency. Start small, share one limiter across workers, and increase the pool only while 429 responses stay at zero.
Is a queue necessary for small volumes?
For a few images processed by an internal script, a direct call with retries is fine. Once users upload images through your product, a queue protects the upload request from slow processing and makes failures recoverable. Our Django integration guide shows one way to set this up.